AI Twitter/X Hots Digest · 2026-10-27 (Tuesday)
Today’s highlights
- GPT-6.1 Terra leans into computer use: OpenAI ships a mid-tier model for cheaper screen-aware, cross-app work; Sam and Greg say it crosses a speed threshold, and it is already in GitHub Copilot, Codex, and OpenClaw.
- Cursor ships two punches the same day: the Agent SDK (agents as code + built-in evals) and DeepSeek V4.1 Flash on the CursorBench cost frontier.
- Skills and multi-agent workflows keep productizing: Theo opens tstack; Grok Bot 0.75.8 puts auto-review rules in chat; Chinese builders demo Claude Code directing while Grok Bot executes.
1. OpenAI GPT-6.1 Terra: cheaper computer use lands in everyday coding paths
Takeaways: @OpenAI announces GPT-6.1 Terra — a faster, cheaper computer-use model that reads the screen, acts across apps, and writes more naturally for all-day workloads. @sama calls out a “new era of computer use”; @gdb says Terra’s computer use now feels faster than unassisted human use. @github / @code say the model is generally available in GitHub Copilot (including VS Code), solving more terminal and C# tasks than GPT-5.6 Terra in early testing at a lower cost than GPT-6.1 Sol.
Why it matters: Computer use moves from launch videos into “default selectable model” slots in Copilot and Codex — competition shifts toward cost-per-task and whether an agent can finish a real GUI workflow.
- OpenAI: GPT-6.1 Terra launch: https://x.com/OpenAI/status/2114780711664398349
- sama: new era of computer use: https://x.com/sama/status/2114818620782248024
- gdb: faster than unassisted: https://x.com/gdb/status/2114814747254432243
- github: Copilot GA: https://x.com/github/status/2114799272634007801
2. Cursor: Agent SDK is live; DeepSeek V4.1 Flash ships the same day
Takeaways: @cursor_ai announces the Agent SDK — define agents as code with Markdown prompts and TypeScript tools; deploy on Cursor’s hosted infra or your own; built-in evals measure every change. A follow-up links the docs. The same day, DeepSeek V4.1 Flash lands in Cursor with every effort level on the CursorBench cost frontier (~$0.60–$0.98 per task).
Why it matters: Cursor is productizing “build your own agent” as an SDK while still racing on model price/performance — the IDE fight expands from autocomplete quality to versioning agents like application code.
- cursor_ai: Agent SDK available: https://x.com/cursor_ai/status/2114793714531102901
- cursor_ai: Agent SDK docs: https://x.com/cursor_ai/status/2114793726602285211
- cursor_ai: DeepSeek V4.1 Flash: https://x.com/cursor_ai/status/2114839997568405608
3. Theo opens tstack: the agent skills he uses every day in Claude Code / Codex
Takeaways: @theo posts “I guess it’s time to announce tstack? I caved.” and publishes his daily agent skills (MIT, for Claude Code and Codex). Follow-ups spotlight full-send (take a change all the way to a merged PR) and council (three providers review until they agree). Repo t3dotgg/tstack was created on 2026-10-24 — today is the author announcement and viral recirculation, not a same-day greenfield repo.
Why it matters: When a frontline tool author open-sources private, dotfiles-grade skills, Agent Skills look less like listicle fodder and more like shareable workflow units.
- theo: tstack announcement: https://x.com/theo/status/2114623574371963360
4. Grok Bot 0.75.8: add auto-review rules right in chat
Takeaways: @ericzakariasson says grok @bot 0.75.8 is stable and rolling out: add auto-review rules in chat and confirm the card; auto-review takes a second look before blocking; Slack approval cards state what they are asking; plugin skills work immediately after install; connectors pick up new tools without reconnecting; x money connects in one tap.
Why it matters: Personal-agent safety gates move from admin YAML into conversational UX — approvals and rules become everyday product surface area.
- ericzakariasson: 0.75.8 rollout: https://x.com/ericzakariasson/status/2114833082956321095
5. Claude Code + Grok Bot: one directs, one executes
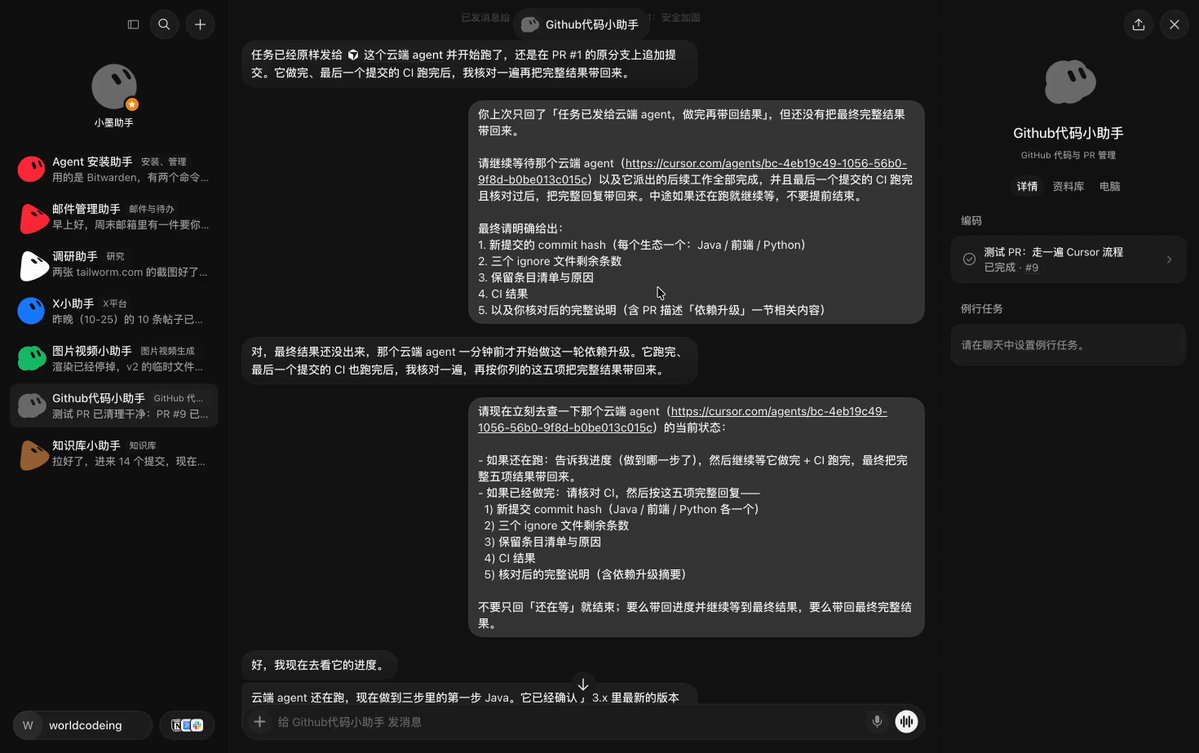
Takeaways: @xiaomovps demos the cursor-grokbot-agents extension so Claude Code (or Codex) can call a Grok Bot inside a Cursor account via the Agent SDK — the Bot keeps its own chat, memory, and tools while the lead agent plans and reviews. The loop: Claude Code scopes work → Grok Bot codes and opens PRs → Cursor Cloud runs tests → the lead agent checks results. Bookmarks outpace likes, a classic “reusable workflow” pattern.
Why it matters: Multi-agent stops being a slogan and becomes a production line you can follow from a phone: scheduler model × worker model × cloud test harness.
- xiaomovps: Claude Code + Grok Bot loop: https://x.com/xiaomovps/status/2114591684407464354
6. OpenCode: permanent sessions hit performance walls; mobile “cures X addiction”
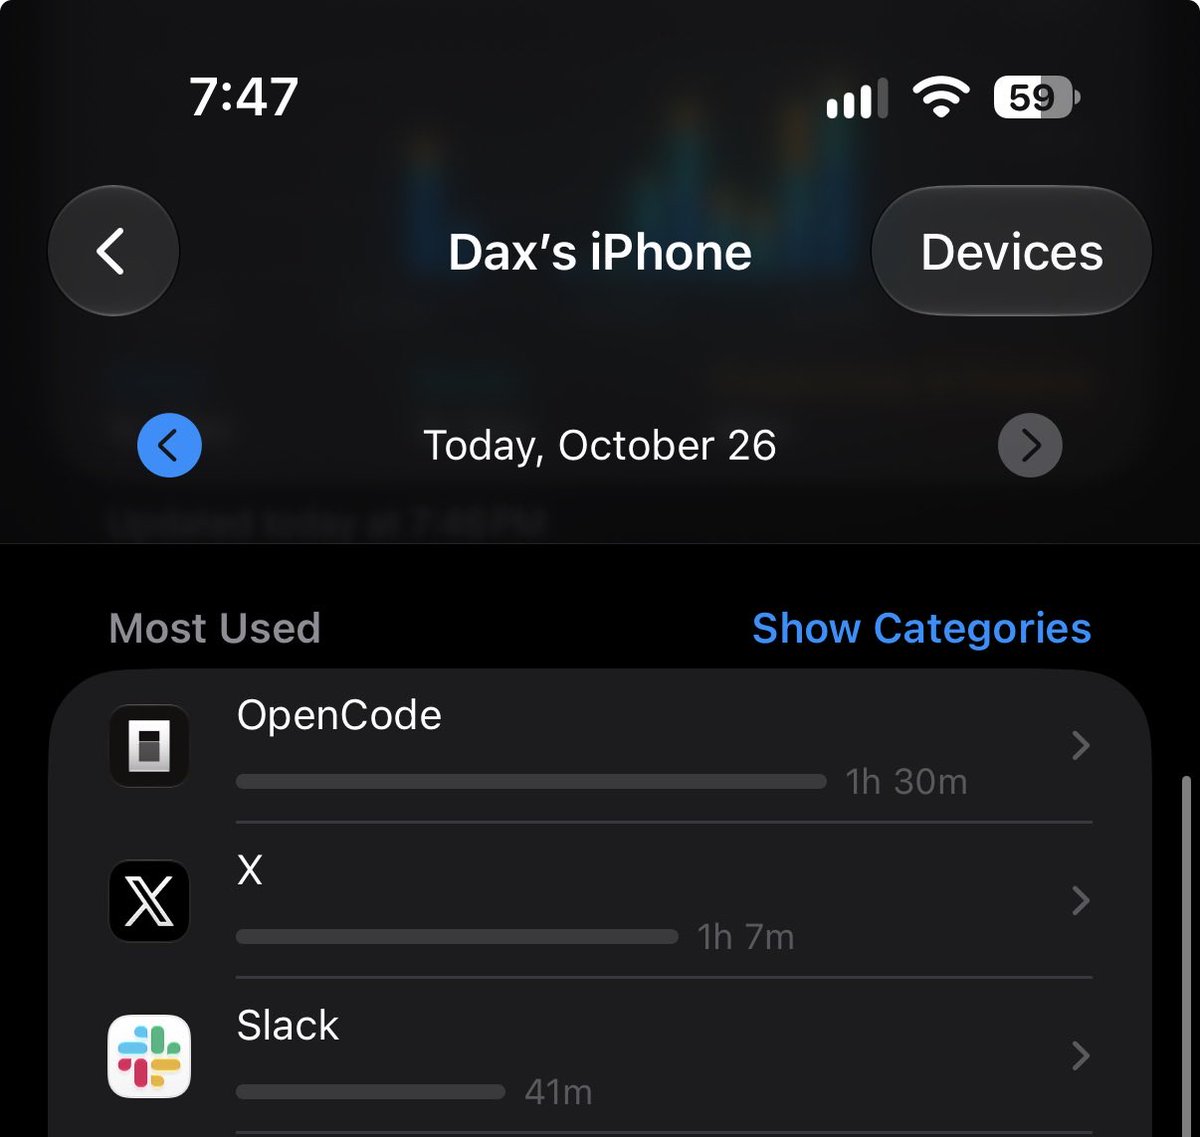
Takeaways: @thdxr says much of the team now runs permanent sessions that never stop — and that has surfaced performance issues they will fix. A second post shows OpenCode mobile and jokes that it is “curing my X addiction.” Together: long sessions are becoming the default, and mobile is fighting for leftover attention.
Why it matters: Open harness pressure tests come from real “never close the session” usage — product debt shifts from feature checklists to session lifetime and mobile UX.
- thdxr: permanent-session performance: https://x.com/thdxr/status/2114849715065860129
- thdxr: OpenCode mobile: https://x.com/thdxr/status/2114866632715853853
7. Meta Muse: alexandr_wang turns a meme video into a game with Muse Wonder
Takeaways: @alexandr_wang posts that muse wonder full helped turn a viral “sperm video” into a playable web game, with a demo and link. It extends the recent personal-agent / “Muse gang” chatter into a shareable micro-product.
Why it matters: Personal agents keep expanding beyond “write my code” into “ship an interactive artifact from a joke” — demos beat changelogs for explaining the product shape.
- alexandr_wang: Muse Wonder game: https://x.com/alexandr_wang/status/2114864218222809294
8. Uncle Bob: building serious software while driving
Takeaways: @unclebobmartin writes that five years ago he would have dismissed “build significant software systems while driving” as optimistic by orders of magnitude — and that it is already happening; he wonders how the next five years will reshuffle priorities before institutions can respond. It continues yesterday’s “leaving CLI for grokbots” thread.
Why it matters: When the Clean Code author uses “coding in the car” as a time anchor, personal agents plus voice/mobile entry points have entered serious engineering self-image, not just demo day.
- unclebobmartin: building software while driving: https://x.com/unclebobmartin/status/2114792205336674657
9. Kimi K3.1 Pro: near the top of Browser Use’s agent benchmark
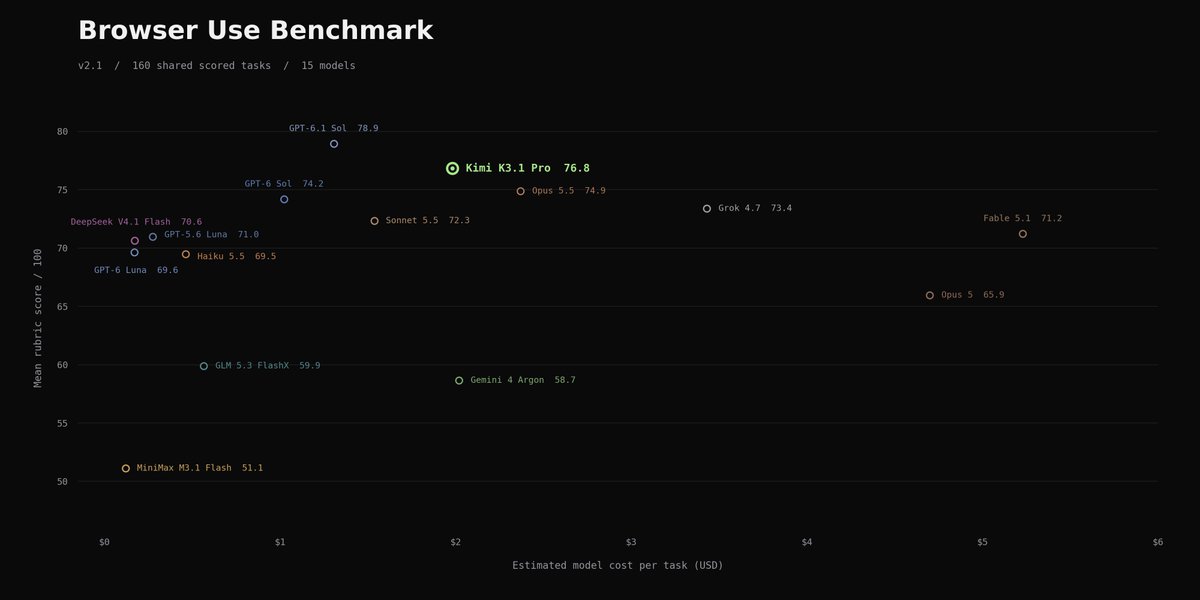
Takeaways: @browser_use posts that Kimi K3.1 Pro scores 76.8 on the Browser Use Benchmark — second only to GPT-6.1 Sol — beating Opus 5.5, Grok 4.7, and Sonnet 5.5 at ~$2 per task, calling it the best Chinese model they have tested by a wide margin (next: DeepSeek V4.1 Flash at 70.6). Kimi’s main launch window was earlier; today’s signal is the browser-use bake-off.
Why it matters: Agent evals are expanding from “can it write code” to “can it finish real browser tasks” — open-weight players are dragging computer/browser use into the cost war.
- browser_use: Kimi K3.1 Pro browser use: https://x.com/browser_use/status/2114807314310156312
10. kunchenguid: every product is just LLM + harness + connectors + machines + UI
Takeaways: @kunchenguid lists ChatGPT Chat/Work, Codex, dots, Claude Web/Code/Cowork/Desktop/Duet, Cursor, Grok Bot/Build, and more — then argues they are all “just LLM + harness + connectors + machines + UI,” asking whether people really want them as separate products. The replies are lively and rhyme with the day’s multi-agent mashup talk.
Why it matters: When product names explode, this five-part anatomy helps more than another leaderboard: are you short a model, a harness, a machine, or a UI?
- kunchenguid: five-part anatomy: https://x.com/kunchenguid/status/2114554647411351966