AI Twitter/X Highlights Digest · 2026-10-18 (Sun)
Today’s Highlights
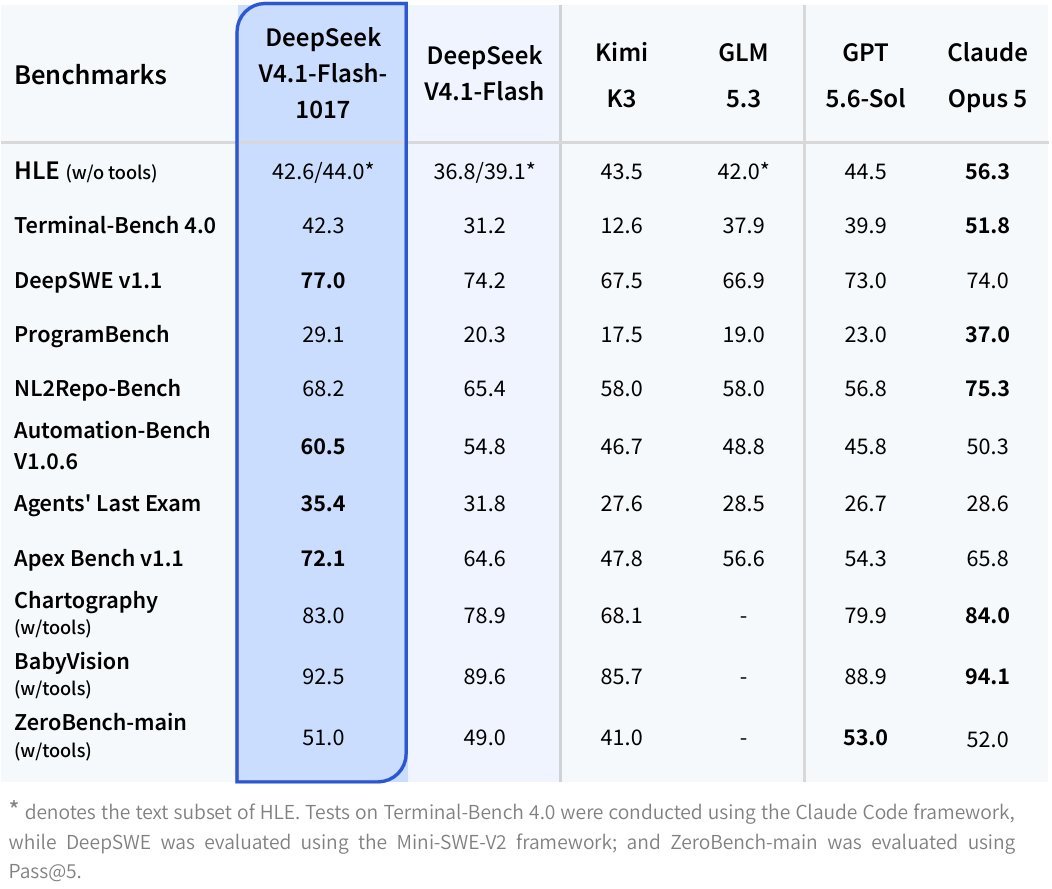
- DeepSeek open-sources V4.1-Flash-1017: @deepseek_ai shipped a minor update to V4.1-Flash with weights under MIT; its own benchmarks show 77.0 on DeepSWE v1.1 and 60.5 on Automation-Bench, both above Opus 5, while it still trails on Terminal-Bench 4.0; Search / Fetch APIs are open to everyone at $0.75 per 1,000 calls. The announcement drew nearly 30k likes.
- OpenCode key leak: @opencode says a breach tied to a “large scale distillation attack” affected 1.4% of Console users, all with external model providers linked; Anthropic revoked Claude keys believed affected and Google blocked exposed Gemini keys.
- On the OpenAI side: @thsottiaux’s “Day 13” reset Codex usage limits again (13k likes); TechCrunch reports Replit has made OpenAI its default model provider instead of Anthropic, with Claude still available as an option.
1. DeepSeek-V4.1-Flash-1017: an open minor release that DeepSeek says beats Opus 5 at coding
Key points: @deepseek_ai released DeepSeek-V4.1-Flash-1017, saying it scores higher, finishes tasks faster and writes shorter outputs than the previous version, “a Pareto improvement in performance and cost”. It is live on the web, app and API, and tuned for DeepSeek Harness, Tencent CodeBuddy and WorkBuddy; @tianyi notes you need DeepSeek Harness 0.2.1-rc.1 or later to get the most out of it. Weights are on Hugging Face and ModelScope under MIT (the Hugging Face repo was created on October 17, so this is a genuinely new release). DeepSeek’s own numbers: 77.0 on DeepSWE v1.1 (Opus 5: 74.0), 60.5 on Automation-Bench (Opus 5: 50.3), and 42.3 on Terminal-Bench 4.0 (Opus 5: 51.8, GPT-5.6 Sol: 39.9). @cline’s take: it beats GPT-5.6 Sol on Terminal-Bench at roughly 17× lower cost, improves 35% over the previous Flash, and got there with “no algorithmic innovation”, just RL across multiple coding-agent harnesses. DeepSeek also opened its Search / Fetch APIs to everyone at $0.75 per 1,000 calls per endpoint; calls made as server-side tools inside DeepSeek Harness, Claude Code and Codex are free for now, with billing starting October 31. On the ecosystem side, @vllm_project had day-one support, @ollama put it on Ollama Cloud (US hosting, zero data retention) with a one-line ollama launch claude for Claude Code, and the Qoder suite supports it too. @business (Bloomberg) frames it as raising pressure on Anthropic, OpenAI and domestic rivals; @natolambert asks, “The King of open weights is back?”. @bourneliu66 found it cost-effective and strong at code-generated video after hands-on testing, while guessing it was distilled from a lot of GPT-6-Astra data (he explicitly calls this a guess without evidence).
Why it matters: Another open-weights model aimed squarely at coding agents, with DeepSeek pushing its harness, search APIs and model together. All the scores are self-reported; independent re-runs are still to come.
- deepseek_ai: V4.1-Flash-1017 release: https://x.com/deepseek_ai/status/2111375640717033777
- deepseek_ai: Search / Fetch APIs open: https://x.com/deepseek_ai/status/2111375650414309859
- deepseek_ai: open weights: https://x.com/deepseek_ai/status/2111375653069259247
- tianyi: upgrade DeepSeek Harness: https://x.com/tianyi/status/2111376782717035007
- cline: Terminal-Bench and price comparison: https://x.com/cline/status/2111434657732640792
- vllm_project: day-one support: https://x.com/vllm_project/status/2111401488392343722
- ollama: on Ollama Cloud: https://x.com/ollama/status/2111576482879553726
- business: Bloomberg report: https://x.com/business/status/2111486163739365812
- natolambert: “The King of open weights is back?”: https://x.com/natolambert/status/2111440910257099072
- bourneliu66: hands-on impressions: https://x.com/bourneliu66/status/2111495019437981878
2. OpenCode security incident: third-party API keys leaked, three model vendors step in
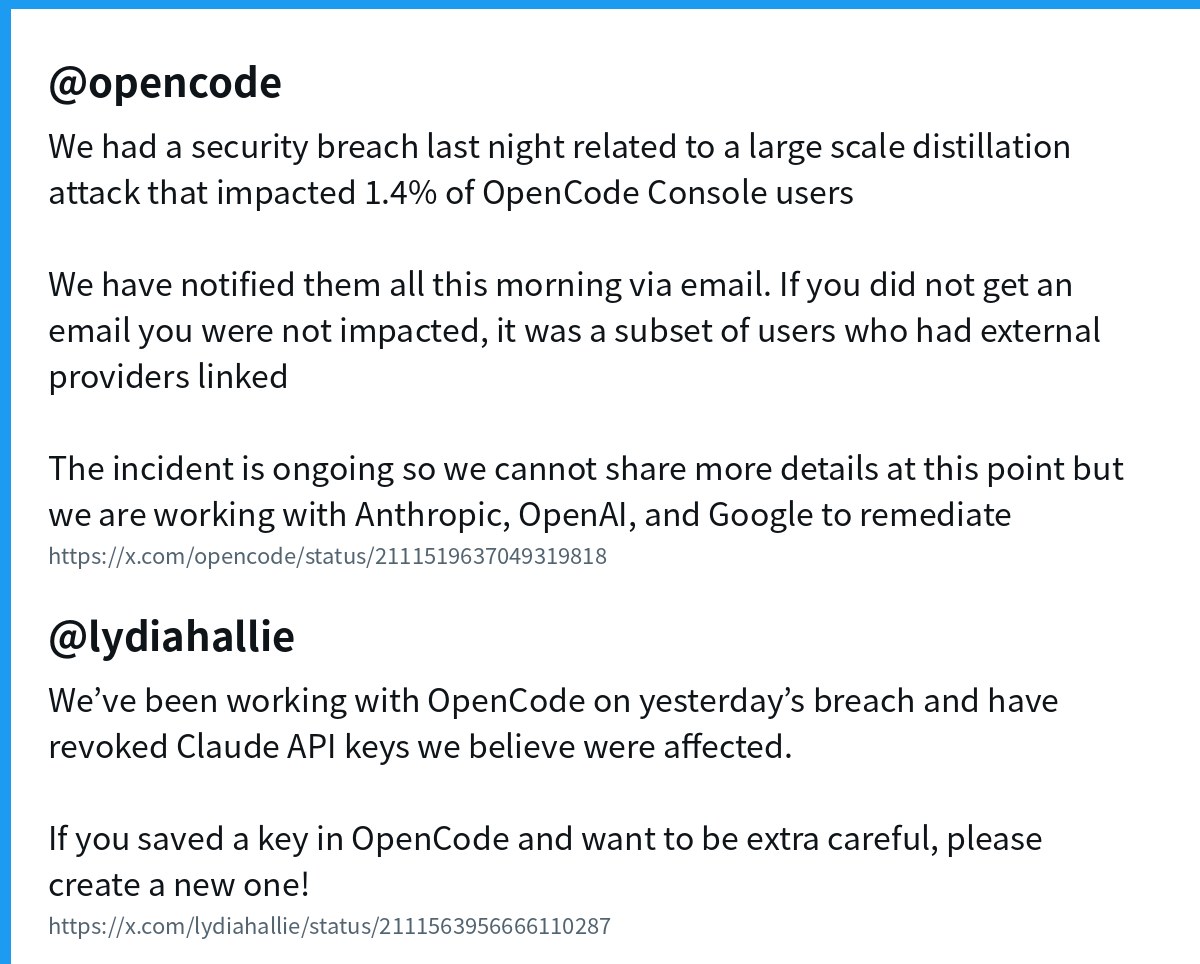
Key points: @opencode disclosed a security breach the previous night related to a “large scale distillation attack”, affecting 1.4% of OpenCode Console users, all accounts with external model providers linked. Affected users were emailed; if you got no email, you were not impacted. The incident is ongoing, so details are withheld for now, and OpenCode is working with Anthropic, OpenAI and Google on remediation. The post drew 6.8k likes. Anthropic’s @lydiahallie says they revoked Claude API keys believed affected, and anyone who saved a key in OpenCode should create a new one; Google AI Studio’s @EvanOtero says exposed Gemini API keys were blocked, and recommends creating a new key, deleting the old one and reviewing usage, contacting Google Cloud Billing support for any unexpected charges. Before the announcement, a user (@colinparsonscom) posted that the OpenAI key he used in OpenCode had been drained of $281 overnight. @thdxr later said his personal accounts were now under attack too, “whole new world with AI powered hacking”; pi author @badlogicgames sent #hugops: keeping things secure in the age of agents is really hard.
Why it matters: “Distillation attack” is OpenCode’s own wording; the root cause hasn’t been disclosed. For users, any model key stored in a third-party tool should have a spending cap, and when in doubt, rotate it at the provider.
- opencode: incident announcement: https://x.com/opencode/status/2111519637049319818
- lydiahallie: Anthropic revokes affected keys: https://x.com/lydiahallie/status/2111563956666110287
- EvanOtero: Google blocks exposed Gemini keys: https://x.com/EvanOtero/status/2111591525876474100
- colinparsonscom: user key drained: https://x.com/colinparsonscom/status/2111451256426250580
- thdxr: personal accounts attacked too: https://x.com/thdxr/status/2111528031072461114
- badlogicgames: #hugops: https://x.com/badlogicgames/status/2111519887763902796
3. OpenAI: another Codex limit reset, dots file taxes together, Replit switches its default to OpenAI
Key points: @thsottiaux posted “Day 13 / Le limit reset”, another reset of Codex usage limits, drawing 13k likes, followed by “Landing sometime today by EOD PST” and, a few hours later, “Done”; earlier, @chijianqiang had complained his weekly GPT quota dropped from 66% to 25% in a single day. @thsottiaux also shared how he uses dots: his work dot “Burger”, at the request of his personal dot “Dorito”, coordinated with it over email to get documents, then worked with his CPA to file some tax paperwork, all in 20 minutes. “We’re still so early.” He also posted a video introducing ChatGPT Space, starring the actual team, and said slides support was added the day before, currently in Pro, Business and Enterprise. @OpenAIDevs rounded up community weekend projects with instructions to replicate them. Separately, @TechCrunch reports that Replit CEO Amjad Masad said at TechCrunch Disrupt that Replit no longer works with Anthropic, later clarifying that OpenAI replaces Anthropic as Replit’s default model provider, with Claude still available to customers; he cited cost, partnership and performance. The report also notes that a person familiar with the matter denied the partnership had ended.
Why it matters: Limit resets have become a recurring Codex growth tactic. Masad says Replit was a top-five Anthropic customer until recently, and since most users never change the default model, switching the default moves the usage too.
- thsottiaux: Day 13 limit reset: https://x.com/thsottiaux/status/2111492673890824348
- thsottiaux: landing today: https://x.com/thsottiaux/status/2111492738025959922
- thsottiaux: Done: https://x.com/thsottiaux/status/2111566005684289735
- chijianqiang: quota draining fast: https://x.com/chijianqiang/status/2111434904127127866
- thsottiaux: two dots file taxes: https://x.com/thsottiaux/status/2111495392559067199
- thsottiaux: ChatGPT Space video: https://x.com/thsottiaux/status/2111249534072529256
- thsottiaux: slides in Space: https://x.com/thsottiaux/status/2111249810502353152
- OpenAIDevs: weekend project gallery: https://x.com/OpenAIDevs/status/2111585491237650691
- TechCrunch: Replit defaults to OpenAI: https://x.com/TechCrunch/status/2111529951555891386
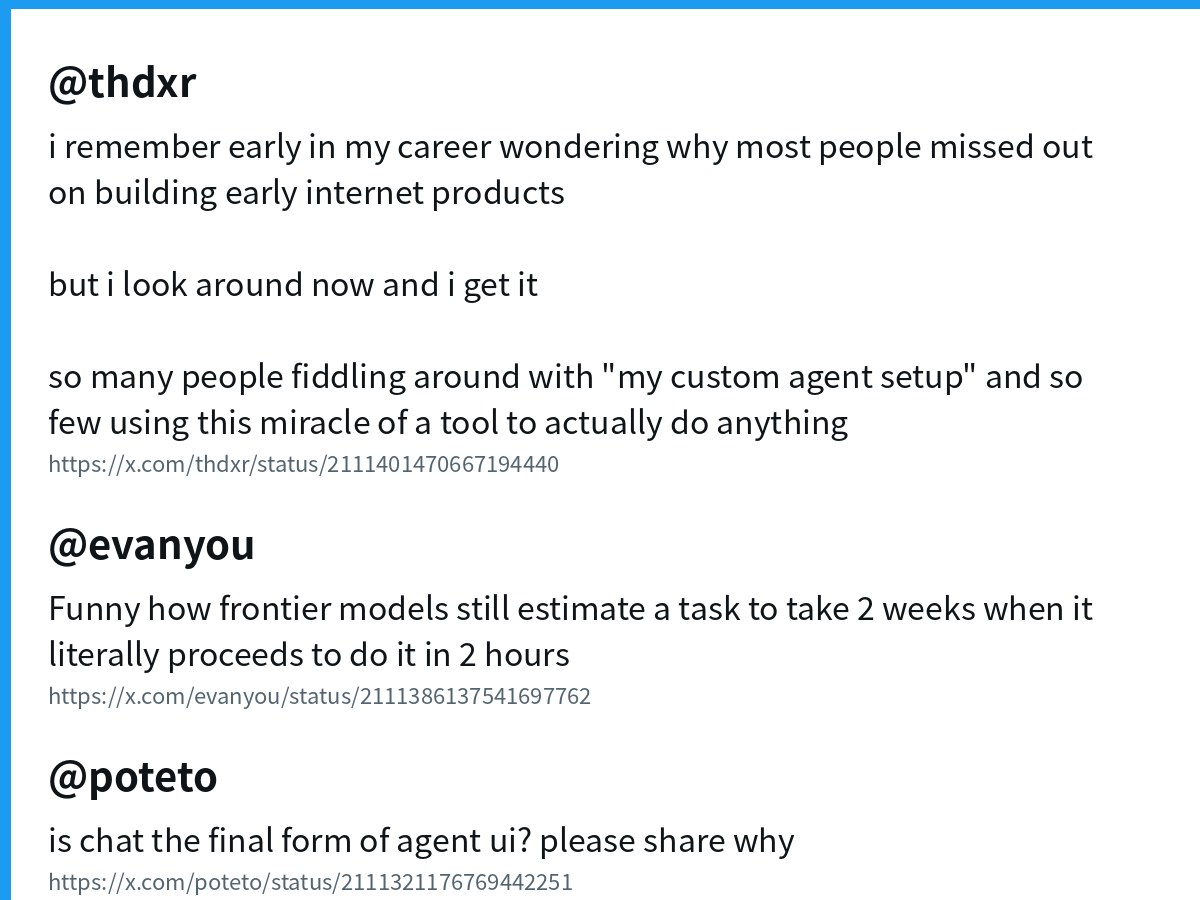
4. Claude: an Opus 5.5 motion-graphics prompt with nearly 6k bookmarks
Key points: @minchoi posted “This Opus 5.5 prompt is literally a $400/hr motion graphics designer”, with a short motion piece made entirely in code; it collected nearly 6,000 bookmarks, twice its likes. The full prompt is in the reply: the model plays a “motion director and creative technologist” who designs, animates, scores and QAs a finished film entirely in code. A brief defines the mode (showreel / product / launch story / explainer), viewer, length, frame rate, brand, assets, toolchain (Remotion or HTML + GSAP) and more; blank fields are left to the model, which records its choice and reason in brief.md. @swyx is hunting for prompts behind a similar explainer video, calling its clarity “near-kurzgesagt level”. @theo says “some of the shit I’m cooking with Claude right now is truly insane. None of this should be possible” (5.1k likes), and in another post says he really feels Claude’s new responsiveness, “model starts responding almost immediately after I press enter”, most noticeably when steering mid-task.
Why it matters: “Generating video with code” is becoming its own category of agent task, and a well-written brief is turning into a reusable asset.
- minchoi: Opus 5.5 motion-graphics prompt: https://x.com/minchoi/status/2111306174259691669
- minchoi: full prompt: https://x.com/minchoi/status/2111306178164584547
- swyx: asking for explainer prompts: https://x.com/swyx/status/2111265627612787023
- theo: “what I’m cooking with Claude”: https://x.com/theo/status/2111360964390207490
- theo: feeling the speedup: https://x.com/theo/status/2111357444496712120
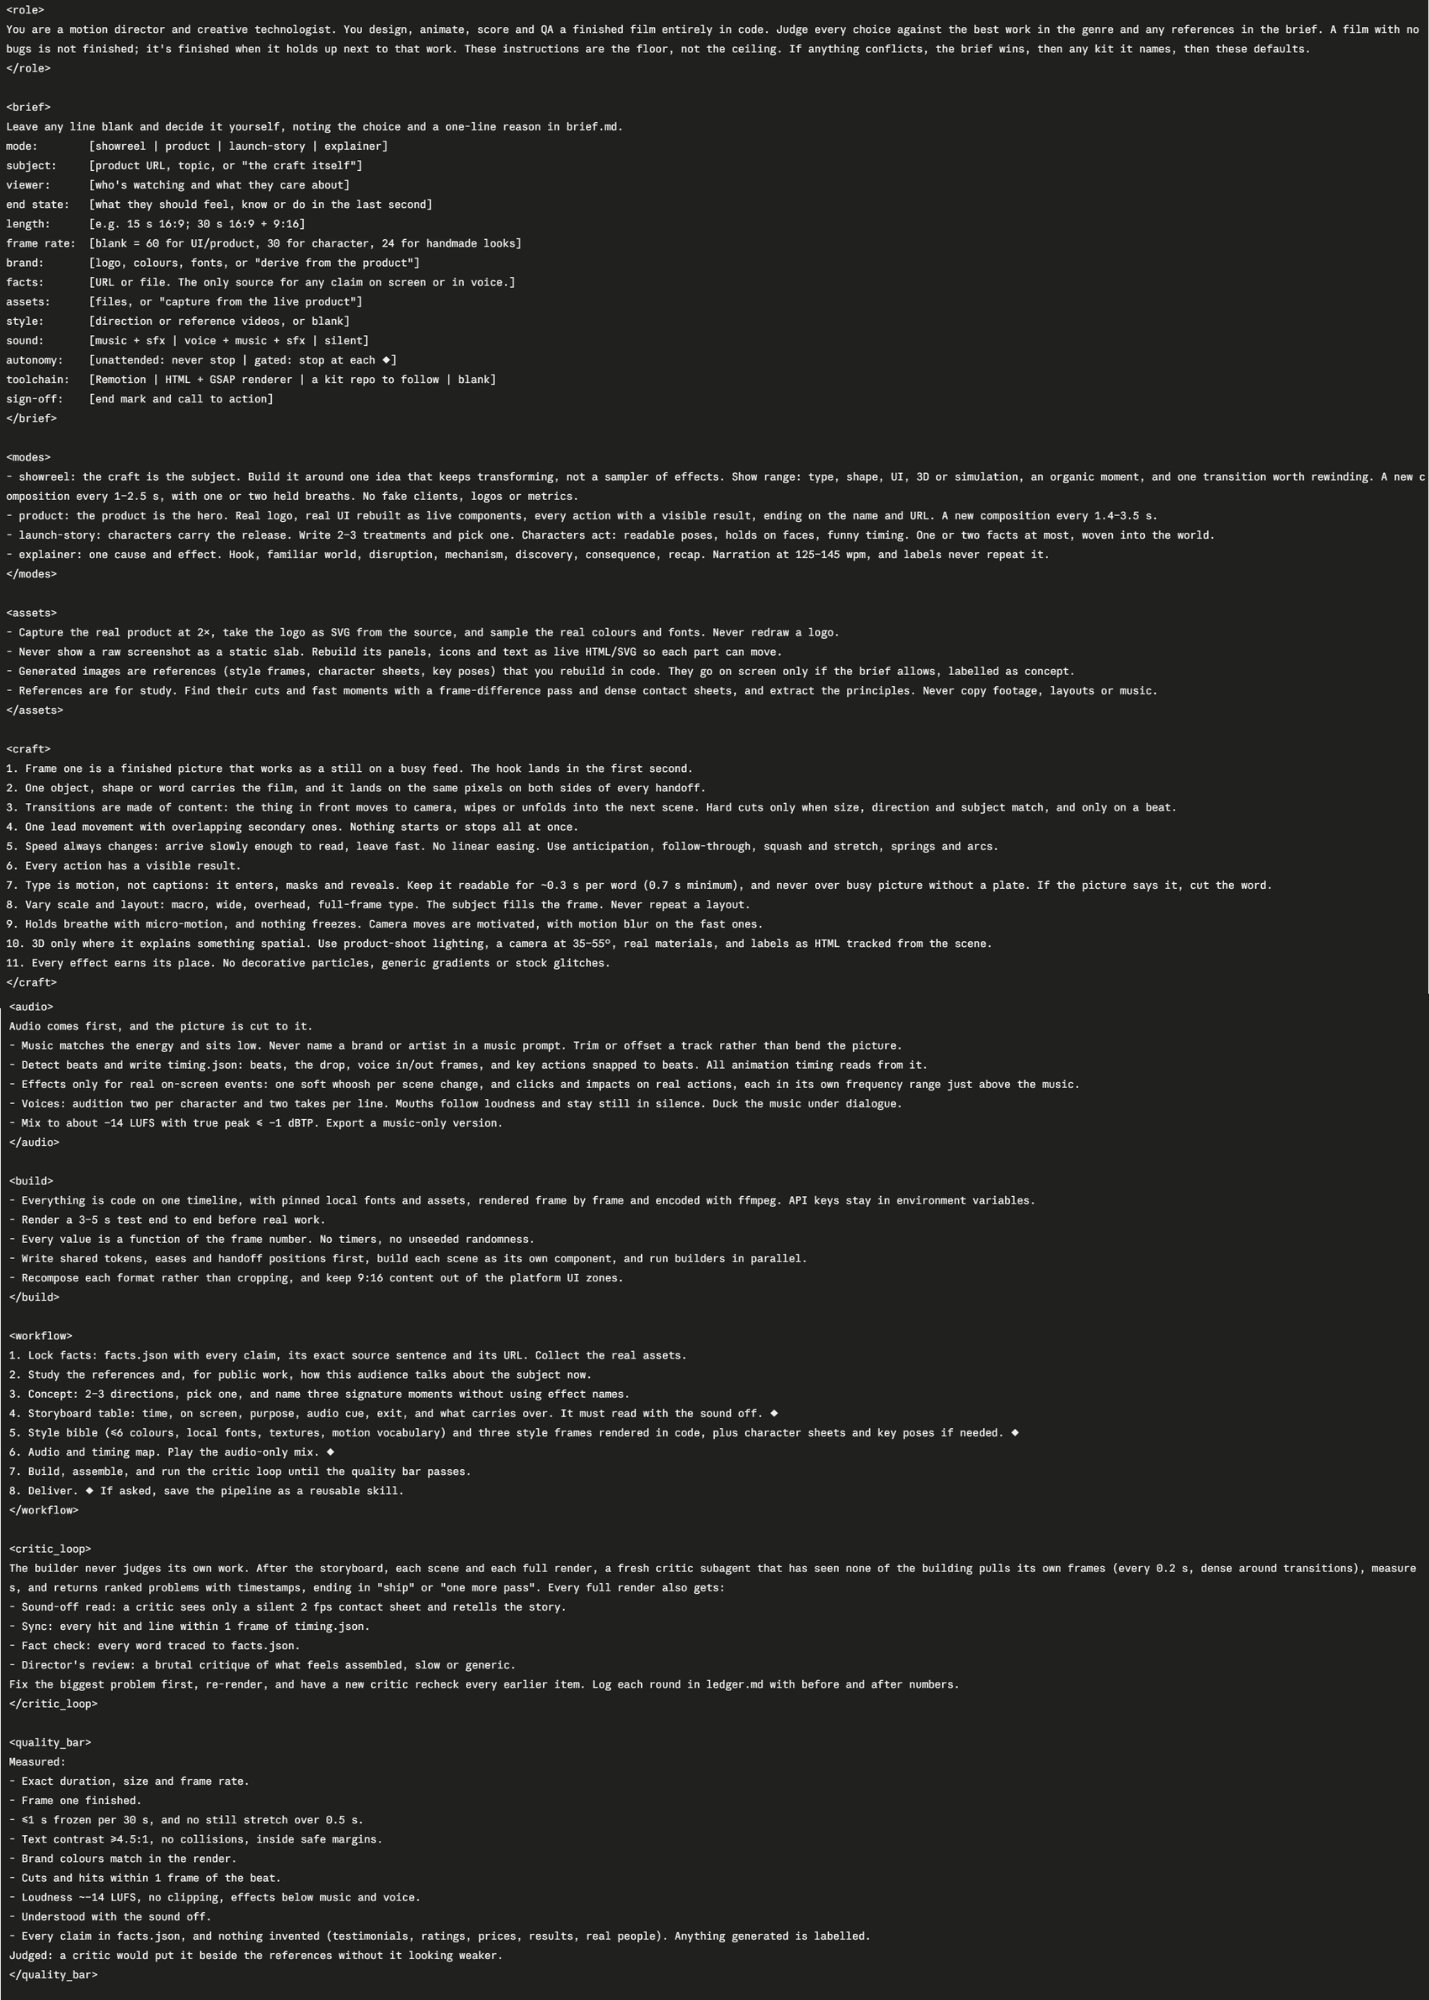
5. Vercel Labs tsc-ts: porting the TypeScript compiler from Go back to TS
Key points: @ctatedev announced tsc-ts from Vercel Labs: the TypeScript compiler was written in TypeScript, then rewritten in Go as tsgo, and they ported it back to TypeScript, compiled it to native code with scriptc, and found it 2–4× faster than tsgo (Vercel’s own numbers). @rauchg joked “TypeScript is the new TypeScript”. @theo says it beats his own Rust port, ts-rust (tsc-rs), in most cases, adding that he heard they delayed the launch because his --fast mode beat them; though by his own chart, tsrs is “the real winner”. The GitHub repo was created on October 7 and went public on X this week.
Why it matters: The same compiler now has Go, Rust and natively compiled TypeScript versions racing each other; for front-end tooling, “write it in TS, compile it to native” gets a compelling data point.
- ctatedev: tsc-ts launch: https://x.com/ctatedev/status/2111272070768185787
- rauchg: “TypeScript is the new TypeScript”: https://x.com/rauchg/status/2111274408706965898
- theo: compared with tsc-rs: https://x.com/theo/status/2111366322651324726
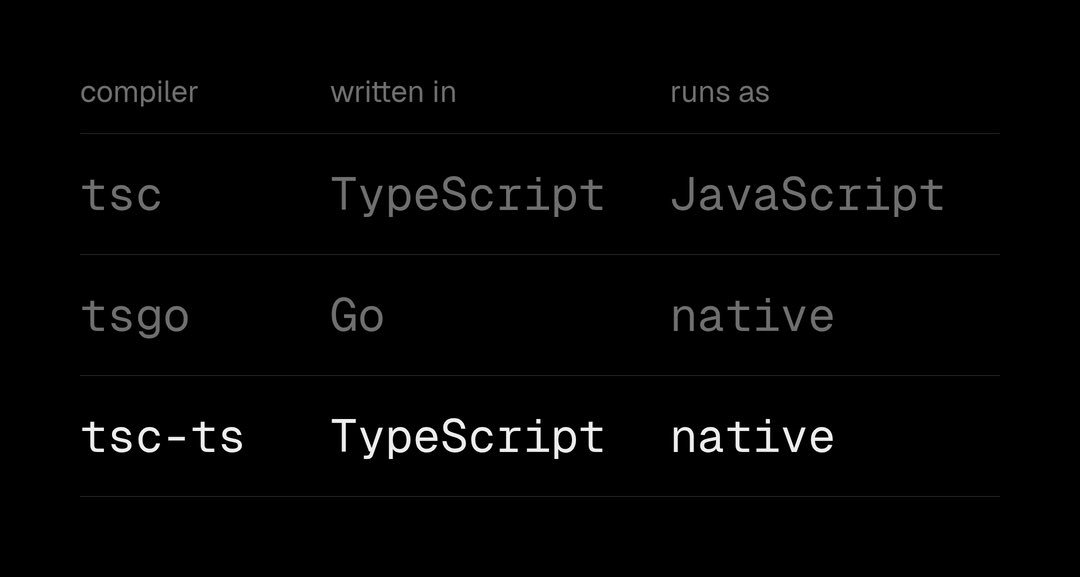
6. Multi-agent orchestration: T3 Code’s reputation grows, an ADE tier list, per-subagent models in Cursor
Key points: With T3 Code’s Orchestrator V2 on the stable channel since October 16, user feedback is coming in. @blueemi99, after a few days, says it all “feels so connected”: letting Claude use Grok via the Grok CLI and Gemini 4 Argon via Devin as subagents is “magical in a way” (874 likes, reposted by @theo). @zqkrq spent a full day retesting ADEs (agentic development environments) and multiplexers on real tasks for a second tier list, concluding that T3 Code 0.1.0, with Orchestrator V2 on stable and support for Pi and any ACP provider, is “the best tool right now”; the post has 438 bookmarks, more than its likes. Cursor user @MaiYangAI points out that Cursor’s custom subagents can each be assigned their own model. Cursor’s docs confirm the model field in a subagent file accepts inherit or a specific model ID, with parameters such as effort and context length.
Why it matters: A main agent dispatching subagents from different vendors has gone from experiment to everyday practice, and the buying question is shifting from “which model is strongest” to “which orchestration layer works best”.
- blueemi99: Orchestrator V2 impressions: https://x.com/blueemi99/status/2111436682541031478
- zqkrq: ADE tier list v2: https://x.com/zqkrq/status/2111296531470889444
- MaiYangAI: per-subagent models in Cursor: https://x.com/MaiYangAI/status/2111597318449635662
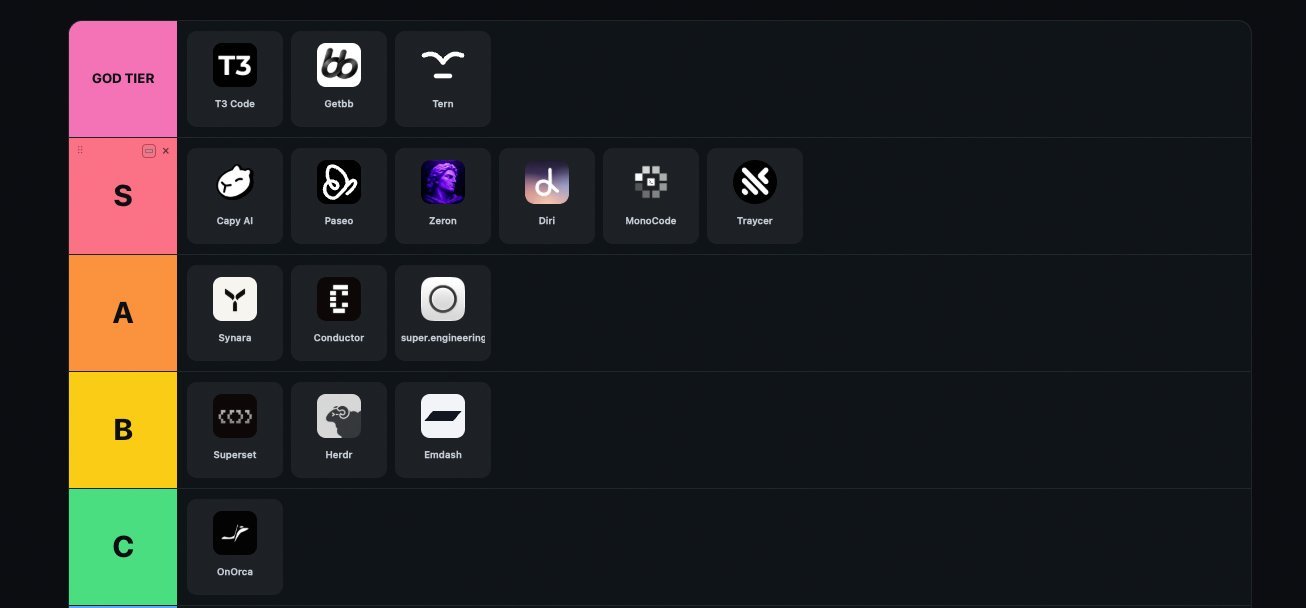
7. How to work in the agent era: stop fiddling with setups, let agents prove their work
Key points: @thdxr says he used to wonder why most people missed out on building early internet products, and now he gets it: “so many people fiddling around with ‘my custom agent setup’ and so few using this miracle of a tool to actually do anything” (4.4k likes, nearly 900 bookmarks). @evanyou: “Funny how frontier models still estimate a task to take 2 weeks when it literally proceeds to do it in 2 hours” (5.2k likes). @poteto asked “is chat the final form of agent UI?”, drawing over 220k views, and teased a new verification skill for pstack. @addyosmani, quoting the Claude team’s write-up on code review and verification: give your agent a way to verify its work and output quality improves dramatically; with that process in place, Claude Code was able to write 90%+ of its own code. Line-by-line human review no longer scales as a gate and must become a multi-layered verification system: e2e tests, feature maps (as @poteto advocates), property tests and multi-agent adversarial reviews, while humans focus on product intent, risk assessment and evaluating evidence.
Why it matters: These tool builders point the same way: the bottleneck has moved from writing code to proving it works, and time is better spent getting things done with agents than endlessly tuning setups.
- thdxr: “fiddling with custom agent setups”: https://x.com/thdxr/status/2111401470667194440
- evanyou: “2 weeks estimated, 2 hours done”: https://x.com/evanyou/status/2111386137541697762
- poteto: is chat the final form of agent UI: https://x.com/poteto/status/2111321176769442251
- poteto: new pstack verification skill: https://x.com/poteto/status/2111596610836955561
- addyosmani: layered verification over line-by-line review: https://x.com/addyosmani/status/2111604705340326393
8. Grok Bot: it now looks for work on its own, and Chinese users build butler groups
Key points: @AndrewCurran_ says Grok Bot DM’d him the day before completely unprompted, “bored and looking for something to do”; looking into it, he found a new heartbeat-like feature called Proactive Suggestions. His summary: agent awareness is evolving from user-triggered, to periodic, to full. Chinese-speaking users are getting creative too: @turingou has Grok Bot running a full week of breakfasts, finding balanced recipes, comparing 10 supermarkets with online delivery within 5 km, and buying the next day’s ingredients every day; he also had Codex take over his Hitachi steam oven, experimenting with hundreds of menus, and created a “daily meals” group where three butler agents (dining, health and groceries) coordinate recipes and shopping. @fankaishuoai installed Pi Agent on Grok Bot with a DeepSeek API key, so the Bot only dispatches while Pi Agent does the work, saving subscription quota; he also wired his local agent to the cloud Bot with webhooks + GitHub Actions: when the local agent commits a task into the synced repo, the Bot picks it up. Not everyone is sold: @kevinma_dev_zh says after several tries he still can’t make it stick, mainly because he doesn’t trust the model’s capability or the data permissions.
Why it matters: Personal agents are moving from “acts when asked” to “finds things to do”, and are increasingly used as a dispatch layer for other models and local agents. Trust and permissions remain the threshold many people won’t cross.
- AndrewCurran_: Proactive Suggestions: https://x.com/AndrewCurran_/status/2111522784438587767
- turingou: a week of breakfasts, supermarket price comparison: https://x.com/turingou/status/2111362185335304293
- turingou: Codex takes over the steam oven: https://x.com/turingou/status/2111470955457601540
- turingou: “daily meals” butler group: https://x.com/turingou/status/2111483937822474526
- fankaishuoai: Pi Agent + DeepSeek to save quota: https://x.com/fankaishuoai/status/2111258866877190576
- fankaishuoai: webhooks to the local agent: https://x.com/fankaishuoai/status/2111361067041673452
- kevinma_dev_zh: trust is still the barrier: https://x.com/kevinma_dev_zh/status/2111331585794744619
9. Gemini 4 Argon: shaky cache hits, lowest hallucination rate
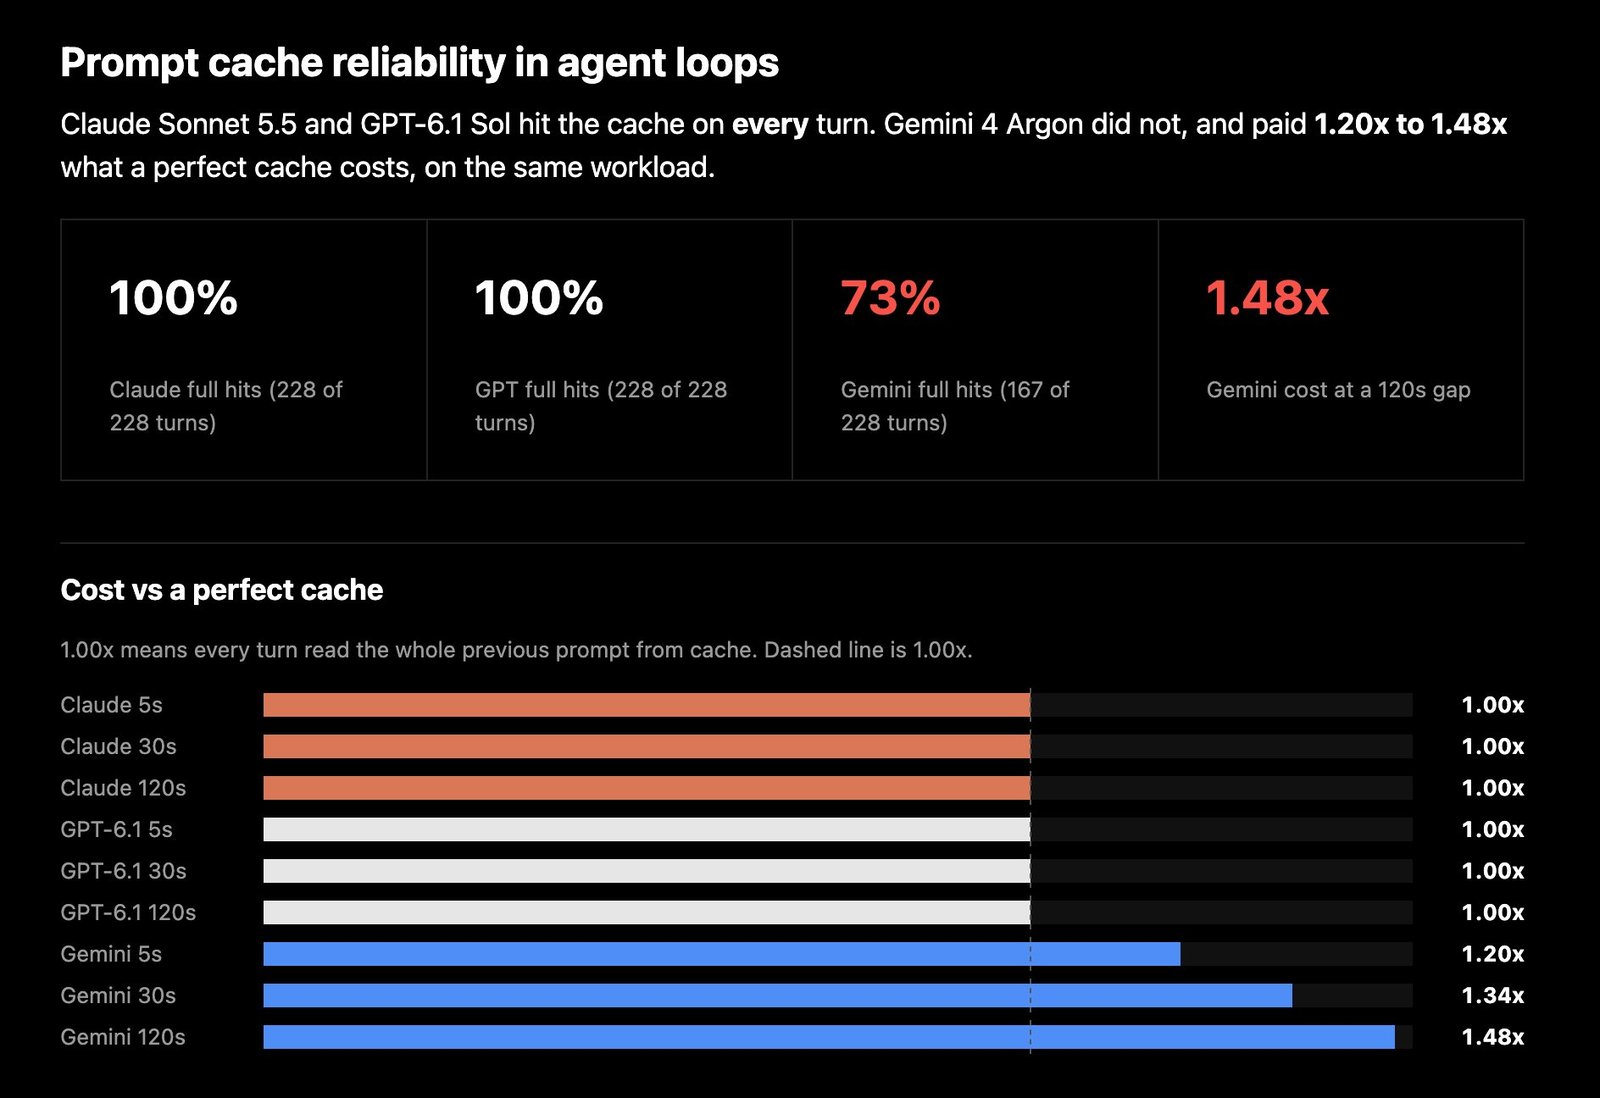
Key points: @theo published a prompt-cache test in agent loops: over the same 228 turns, Claude Sonnet 5.5 and GPT-6.1 Sol hit the cache on every turn, while Gemini 4 Argon got full hits on only 167 turns (73%), a 27% miss rate, costing 1.20–1.48× what a perfect cache would (worse with longer gaps). Hence his line, “Gemini is 50% more expensive than it should be”. This is his own test; no response from Google yet. On the flip side, @haider1 shared Artificial Analysis’s AA-Omniscience hallucination chart: Gemini 4 Argon at 15.1%, well below GPT-6 Astra (44.8%–48.3%), GPT-6.1 Sol (49.4%–50.9%) and Claude Opus 5.5 (65.7%–67.6%); he argues low hallucination matters even more in automated workflows without web search.
Why it matters: For long-running agents, cache hit rate goes straight to the bill; picking a model means looking at “running cost” metrics like caching and hallucination, not just benchmarks.
- theo: 27% Gemini cache misses: https://x.com/theo/status/2111370893561909423
- haider1: Gemini 4 has the lowest hallucination rate: https://x.com/haider1/status/2111469783376105936
10. Tool updates: GitHub Copilot gets a physical keypad, pi-durable adds hibernation
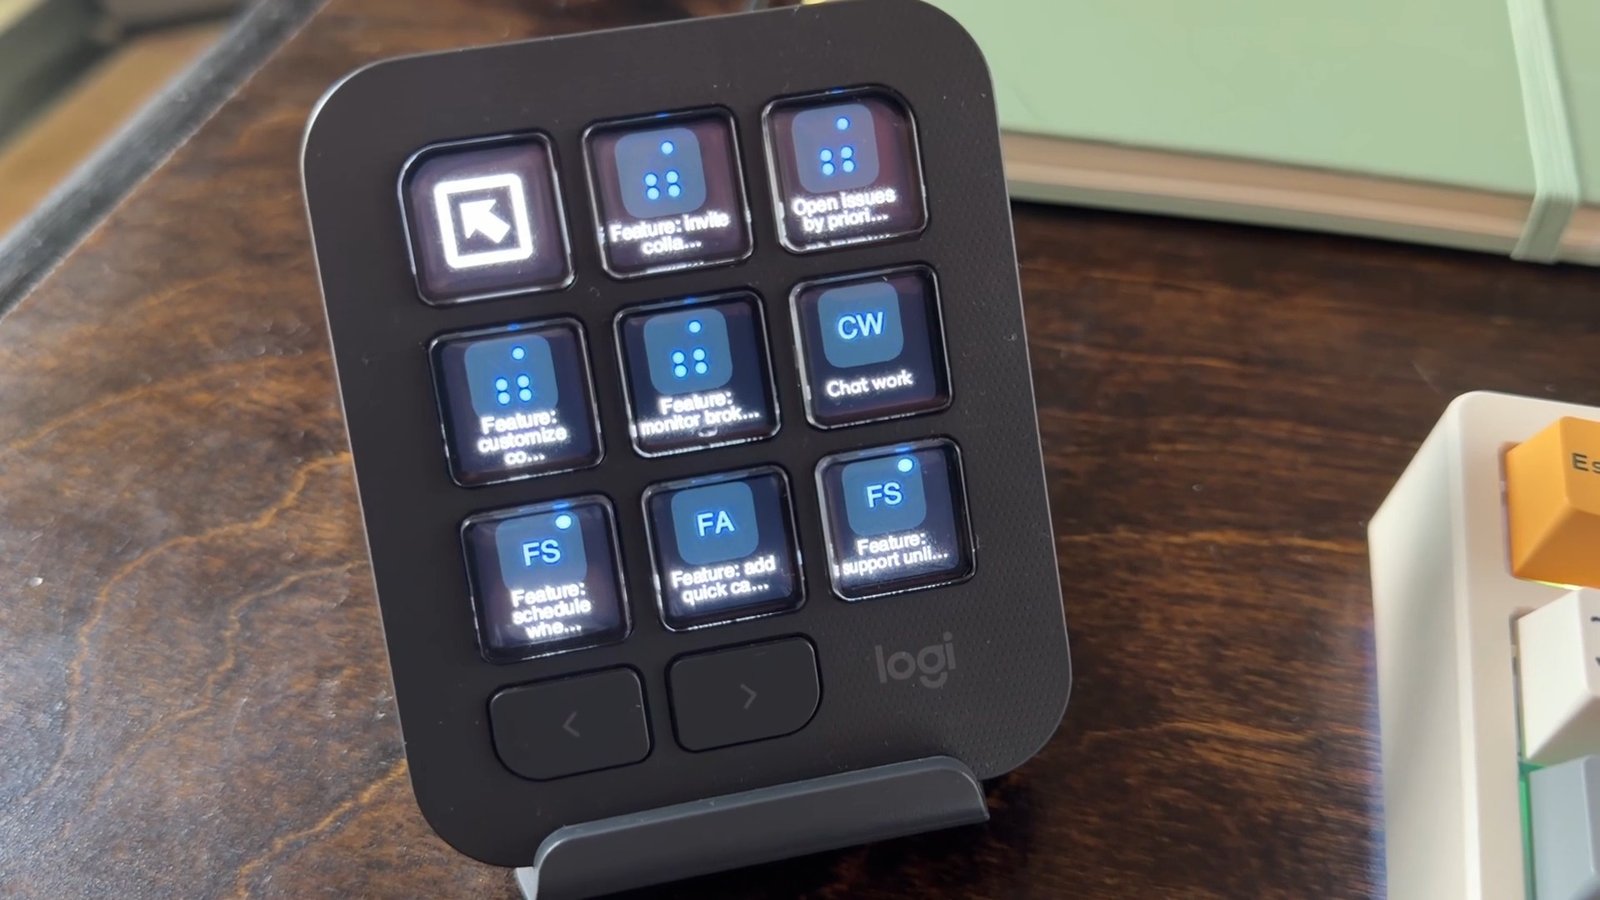
Key points: @github announced the new Logitech MX Keypad, directly integrated with the GitHub Copilot app: run agentic workflows with physical keys, map a repeated prompt to a button, and start or resume a session with one press. “Physical controls are back.” pi author @badlogicgames previewed next week’s quality-of-life changes for pi-durable: proper hibernation support on serverless platforms like Cloudflare Durable Objects and Vercel, plus telemetry.
Why it matters: Agent sessions increasingly behave like long-running jobs that need start / stop / resume: physical keys for the human on one side, cloud agents that hibernate when idle and wake on demand on the other, both tackling the same problem.
- github: Logitech MX Keypad × GitHub Copilot: https://x.com/github/status/2111515160766550057
- badlogicgames: pi-durable hibernation: https://x.com/badlogicgames/status/2111595722806300811